Generalizing MLPs with dropouts, batch normalization, and skip connections
A simple age-gender classification model using Arcface embeddings and MLPs
I trained a simple age-gender classification model using ArcFace embeddings and MLPs. Check out the paper https://arxiv.org/abs/2108.08186 and the code https://github.com/tae898/age-gender/
MLPs are stacks of fully connected layers with nonlinear activations. Many people have tried to improve them for faster convergence and improved performance, but systematic testing methods are often lacking. In our work, we propose a generalized MLP architecture that integrates dropouts, batch normalization, and skip connections, and we evaluate its effectiveness on age and gender classification tasks.
Our architecture introduces two key building blocks: the residual block and the downsample block. Both blocks utilize an Independent Component (IC) layer, comprising batch normalization and dropout, to whiten inputs before each fully connected layer. The residual block includes skip connections to facilitate training deeper networks and is defined as:
Dropout regularizes the MLP. It also lets me estimate uncertainty with Monte Carlo (MC) dropout. In a Bayesian framework, the posterior predictive distribution is obtained by marginalizing over the neural network weights :
Since this integral is intractable, MC dropout approximates it by performing multiple stochastic forward passes with dropout enabled during inference, effectively sampling from the posterior distribution of the weights.
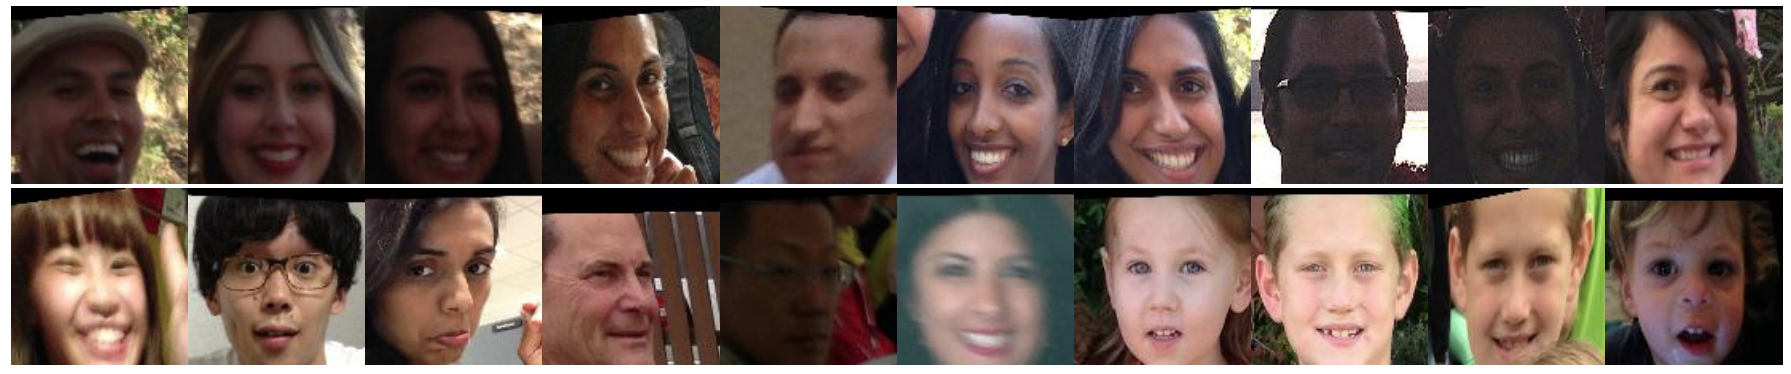
We tested our architecture on the Adience and IMDB-WIKI datasets for age and gender classification. Preprocessing steps included using RetinaFace for alignment and ArcFace for feature extraction, resulting in 512-dimensional vectors as inputs. Our empirical results show that whitening inputs before every linear layer and adding skip connections lead to improved convergence speed and accuracy compared to variants without these components. MC dropout also lets the MLP estimate how confident it is in each prediction.